· 7 min read · updated
Riding in the Cab: Two Cameras, One Renderer
How Traluno draws its train cab view: a second camera in the same three.js renderer, a scissored viewport, recording inside the frame, a seat for every ride.
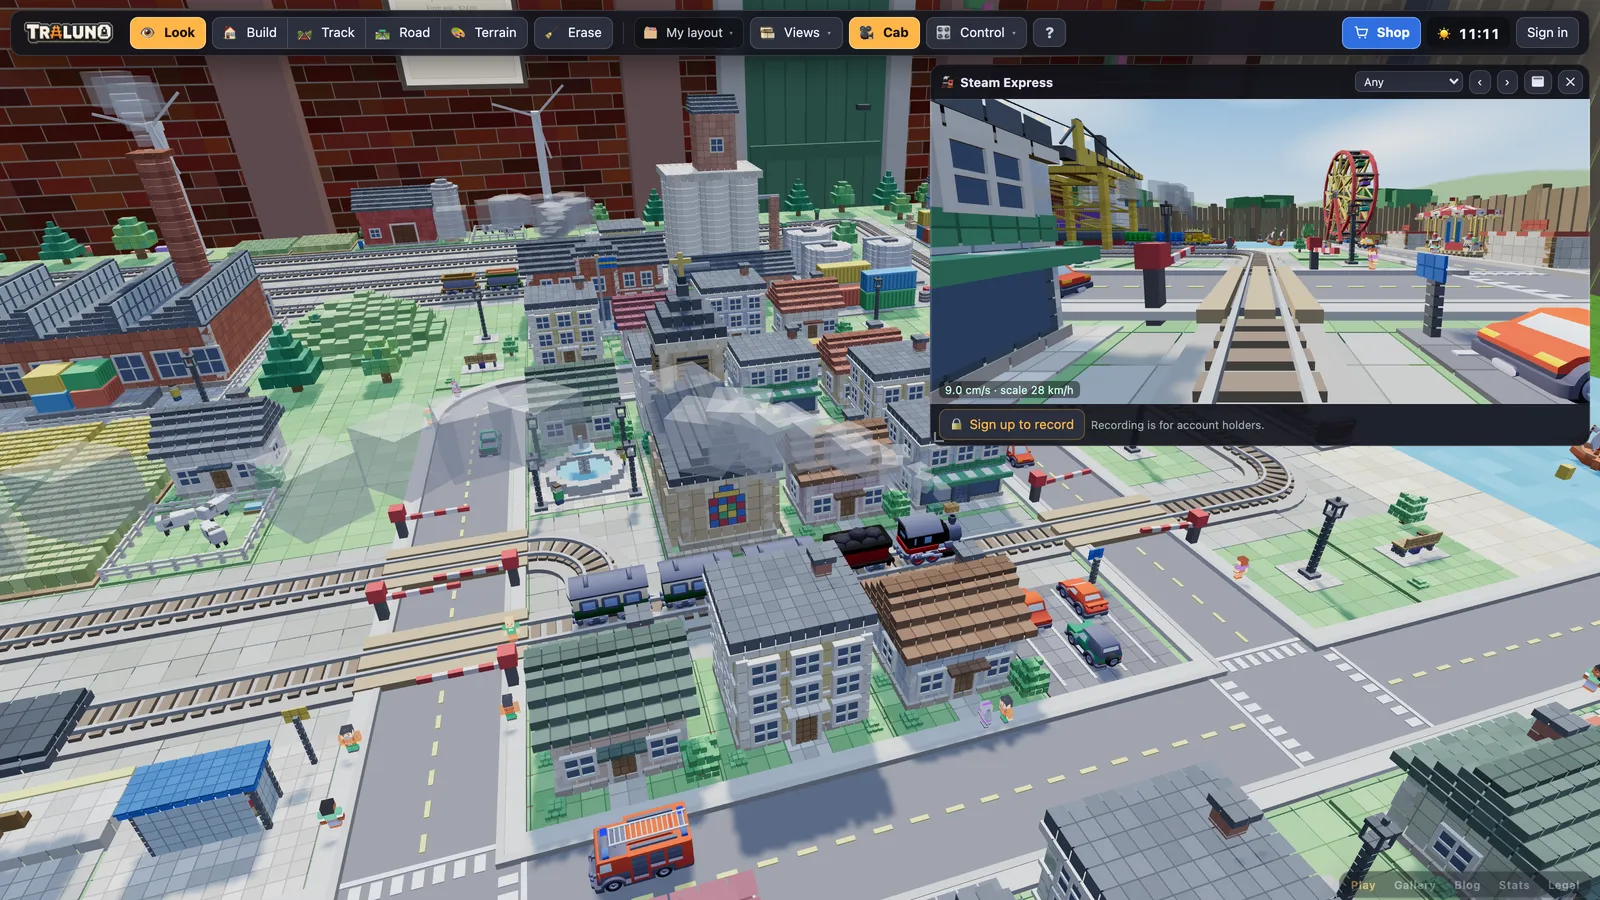
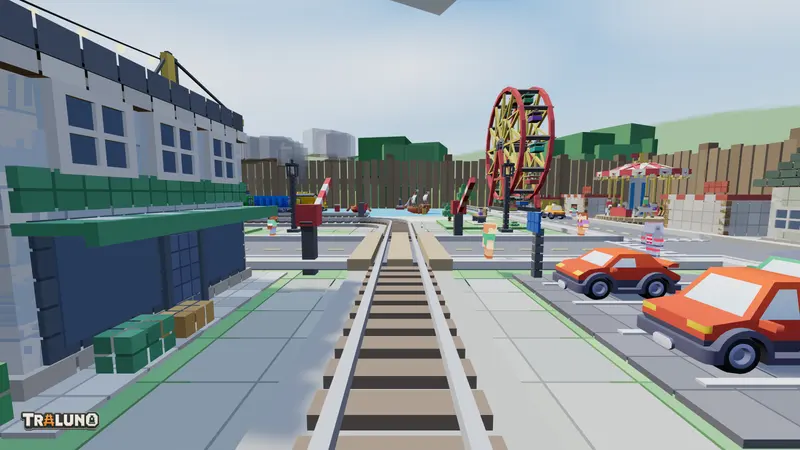
The train cab view started as a small thing: click a train, get a window showing what the driver sees. Model railway operators have done this with real cameras at least since Lionel's Railscope, "a video camera inside a locomotive allowing you to see your railroad from the engineer's perspective" (Finescale Railroader), and it is the one view that makes a layout feel like a railway rather than a diorama.
In Traluno the cab view is a second camera drawn by the same three.js renderer as the main view, into a scissored viewport, and building it forced two decisions that were more interesting than the feature itself. This post is how it is built; the cab ride guide is how to use it.
A second camera in one renderer
The obvious implementation is a second renderer drawing a second view into a second canvas.
Do not do this. A second renderer means a second WebGL context, and contexts are rationed: the three.js manual puts the browser's limit at "typically around 8", says the oldest context is lost as soon as you create the ninth, and points out that nothing can be shared between them (three.js manual: multiple scenes). On some machines the second context simply fails to appear. When that happens inside a React effect, the exception escapes the effect, and with no error boundary to catch it React unmounts the entire component tree (React docs). The failure mode is not "no cab view". It is a blank page.
So the cab view is a scissored inset in the same renderer, which is the approach the same manual recommends for many views on one page. Every frame, straight after the main render, the engine measures where the cab window sits on screen, sets both the viewport and the scissor rectangle to that box, and renders the scene again from the cab camera. WebGL counts rows from the bottom of the canvas and the page counts from the top, so the box is flipped on the way in, and the camera's aspect ratio is taken from the box, so a resized window never stretches the picture. With the scissor test on, the renderer's automatic clear is confined to the box too, which is what leaves the main view around it intact. Then the viewport and scissor go back to the full canvas. One context, no second copy of any texture or buffer, and nothing that can fail independently of the main view.
The consequence is that the cab window in the DOM is not a picture. It is a frame around a hole. Its title bar and footer are solid, and the middle has to stay fully transparent, because anything drawn there (a background colour, a border-radius fill, a loading state, the frosted blur the game's other floating panels have) covers the inset the renderer is painting underneath.
Recording has to happen inside the frame
Recording the cab view means copying the inset out of the drawing buffer.
That copy only works inside the same animation frame as the render. Read it later, in a timeout or in the next frame, and you get an empty buffer: unless a WebGL context is created with preserveDrawingBuffer, "after compositing the contents of the drawing buffer shall be cleared" (WebGL specification), and Traluno's is not.
So the copy is the last step of the cab render itself. Straight after drawing the inset, in the same function, the engine copies that rectangle of the canvas into a small 2D canvas and stamps the wordmark in its corner. The recorder never touches WebGL at all: it streams that 2D canvas at 30 frames a second into a MediaRecorder. Screenshots obey the same rule from the other side. They are copied after the main render and before the inset is drawn, which is what keeps the cab window out of the picture.
It is an unpleasant coupling and there is no way around it. It is written down in the code next to the copy, because it is exactly the kind of thing a later refactor moves somewhere tidier and breaks.
Anything you can sit in is a ride
The generalisation is the part worth stealing.
The cab camera needs a thing that moves and a place to put the eye. A train has both. So does a road vehicle. So does a pedestrian. So does a carousel horse, and a ferris wheel gondola.
There is now one flat list of ridable things, with trains first so that an index which used to mean "train number three" still means that. Everything else appends after them, and the arrows on the cab window walk the whole list.
A train's eye rides at the nose of the locomotive, three units above the rail head, and looks at a point sixteen units further on. That point is found by walking the track itself rather than projecting along the locomotive's heading, so on a curve the view leans into the bend instead of staring off the rails. The walk has one rule: it reads the route the train has already chosen and never chooses one itself. It runs over cells the train has not reached, and a camera that picked a branch there would pin the train to a choice made before somebody threw the switch. Control trains and switches explains why a train's route through a turnout is locked.
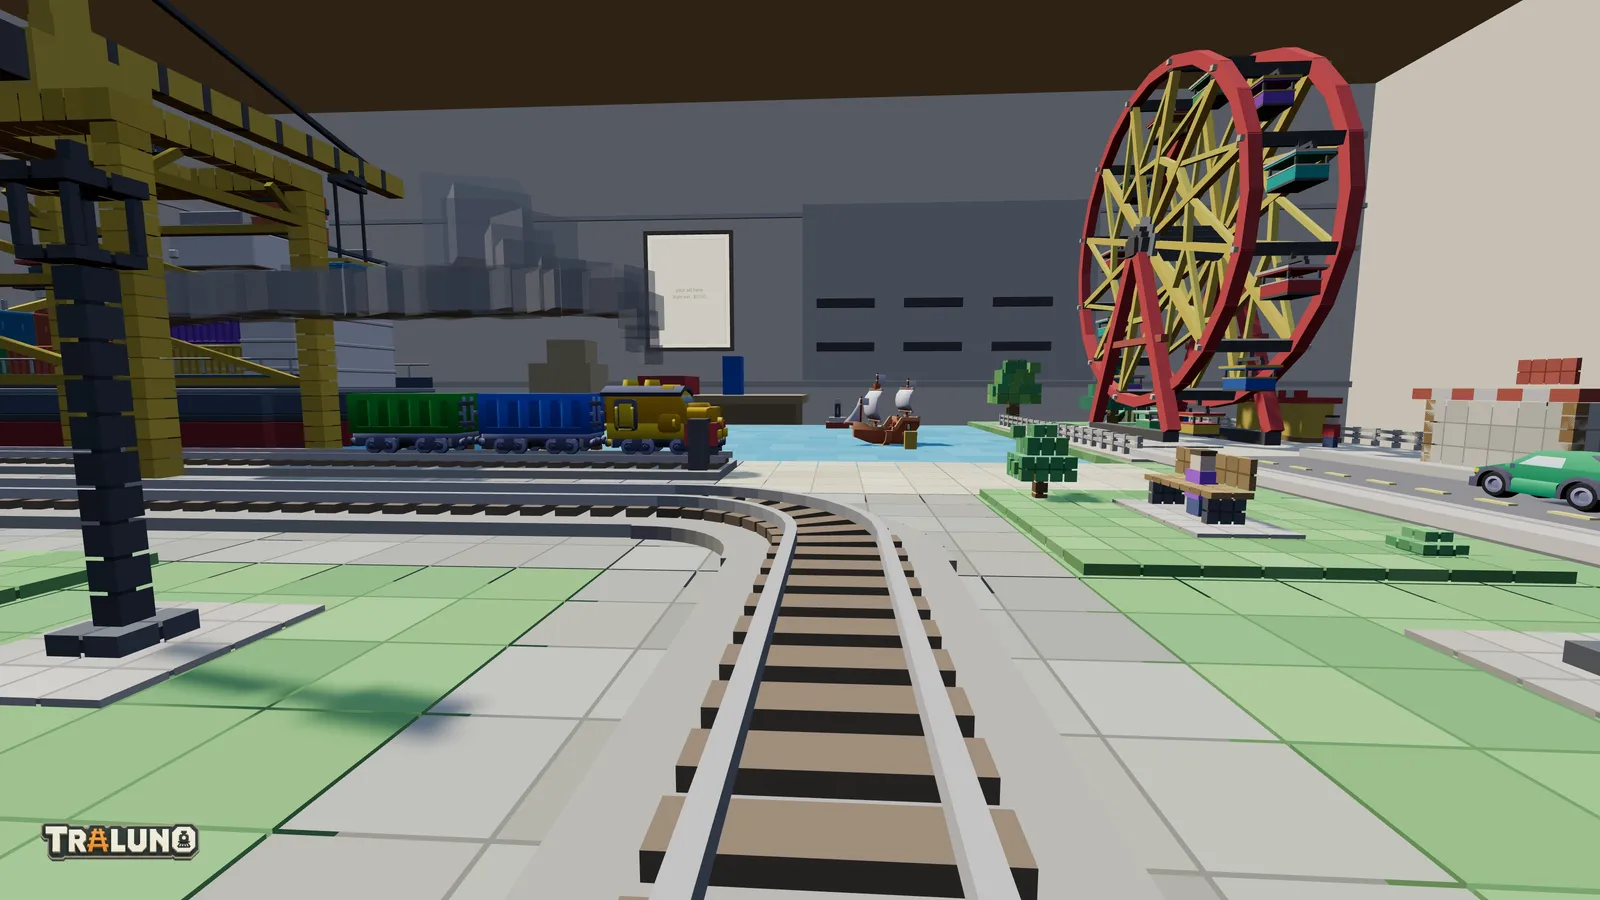
A part of an animated model becomes ridable by declaring a name and a camera, an eye position and a look-at point, in its own local frame. The engine puts both through that part's world matrix every frame.
That last detail is the whole trick. The carousel horse bobs up and down and rotates around the centre; the gondola counter-rotates so it stays level while the wheel turns. Neither of those behaviours had to be described to the camera system. They are already in the part's matrix, because that is what makes the horse bob, and running the eye through the same matrix means the camera inherits every bit of it for free.
Put the eye clear of the structure
One practical note, learned more than once.
The ferris wheel gondola's camera was first placed level with the seat, which is where a passenger's eye is. The view was solid red girder.
The gondola hangs between the wheel's two rim rings, at the same radius as the rings themselves. An eye at seat height looked straight along a ring, so the ring filled the frame from edge to edge and nothing else showed. The fix moved the eye sideways, along the wheel's axle and just outboard of the rim, looking out and down, so the ring is behind the camera instead of in front of it.
The other seats had their own versions. A car's camera at the centre of the car was inside the bodywork, and the view was its own roof and wheels; it now sits at the nose, like a train's. A carousel horse's eye sits ahead of the brass pole, which otherwise fills the middle of the picture.
The general rule: the camera position that is physically correct is often the one with the worst view, because real vehicles have interiors and these do not. Place the eye where the view is, not where the passenger would be.
What it changed about the game
A camera at rail height changes the standard everything else is built to. Every shortcut taken on the assumption that nobody would ever look at the layout from down there stops being a shortcut.
From the cab, a crane tie at train height is not a detail. It is the next thing you hit, and the number every structure over the track now has to clear is in the loading gauge. A one-cell gap in the track, a few pixels wide from standing height, fills the window; Lay Your First Loop has the classic case. A feature that changes where the player can stand changes what has to be right.
- camera
- engine
- rides